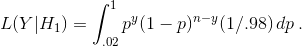i agree, it is a toy problem to illustrate a principle. i have no problem with the principle behind it (Bayes, likelihood ratio tests, etc), just that i don't see how to do this in reality, since, in reality, we can't just assume whatever prob we want if we're actually trying to answer this question.
so here's an approach we could take:
we want to construct a likelihood ratio test of the form
p(live|God)/p(live|not God)
based on data. one way to do this is to look at everyone that got lost over the past, say, 100 years and see how many of those lost lived. so we can estimate
p(live)=(#live)/(total # that got lost).
but in order to come up with p(live|God) and p(live|not God) we have to separate the # who live (numerator) into those that lived by chance and those that lived due to God helping them find water. we could then construct the likelihood ratio test.
the crux of the argument i've been making is that i can't see any way to meaningfully do this. therefore, although you've showed this test is theoretically possible, i can't see how it is possible in practice, as the only way we could separate the #live into those saved by God and those saved by random chance is to use anecdotal (self-reported) evidence.
would you agree?
I'm pretty happy with just assuming under H1 that the God we're talking about isn't a slacker, and so the probability that the explorer lives under H1 is 1.
That said, the problem you've brought up is a standard problem in Bayesian inference, namely, that we may have one or more parameters in our models whose values we do not know. The correct way (both theoretically and practically) to deal with this situation is to represent our state of knowledge about the parameter by using a probability distribution.
In the current problem, we "know" that the probability that an explorer finds water randomly on his own is 0.02. Even if we don't know how much help God would be, it seems reasonable to assume that with God's help the explorer doesn't do any worse than random chance. So under the God hypothesis (H1), it seems reasonable to say that the probability
p of finding water is in the interval [.2, 1]. If we are unwilling to make further assumptions about p we could assume that all values in that range are equally likely, or in other words that p has a uniform distribution on the interval [.2, 1]. We then model each explorer's outcome (lives or dies) as a bernoulli random variable, Y_i.
Under H1 (God), our model is
Y_i | p ~ bern(p)
p ~ uniform[.02, 1] .
Under H2 (random), our model is
Y_i ~ bern(.02) .
Under H2 (random), the likelihood is as before: .02^2 = .0004 .
Under H1 (God), we now need to find the
marginal likelihood, a continuous weighted average of the likelihood, averaged over the possible values of p (.02 to 1), with the weights for each possible value given by the prior distribution (actually, density) on p. The uniform density on [.02, 1] has the constant value 1/.98 = 1.02 (approx). Thus, we find the marginal likelihood by integrating the binomial likelihood function times the prior on the binomial parameter p:
Our data consist of 2 explorers, both of whom got lost, but found water and lived. Thus n=2 and y=2. Plugging those values into the above expression and carrying out the integration, we find that the (marginal) likelihood under H1, L(Y|H1) = .34013.
Thus the ratio of the marginal likelihood under H1 and the likelihood under H2, customarily called the
Bayes factor, is .34013 / .0004 = 850.
Thus, the weight of the evidence in favor of H1 over H2, where H1 reflects our uncertainty about God's helpfulness, is 850, about a third of that for our omnipotent God, but still strongly favoring H1 over H2.